Two ways to get web data
If you need data from websites at scale, you can:
- Use raw proxies with your own scraper (requests, Scrapy, Puppeteer, Playwright) and handle blocks yourself.
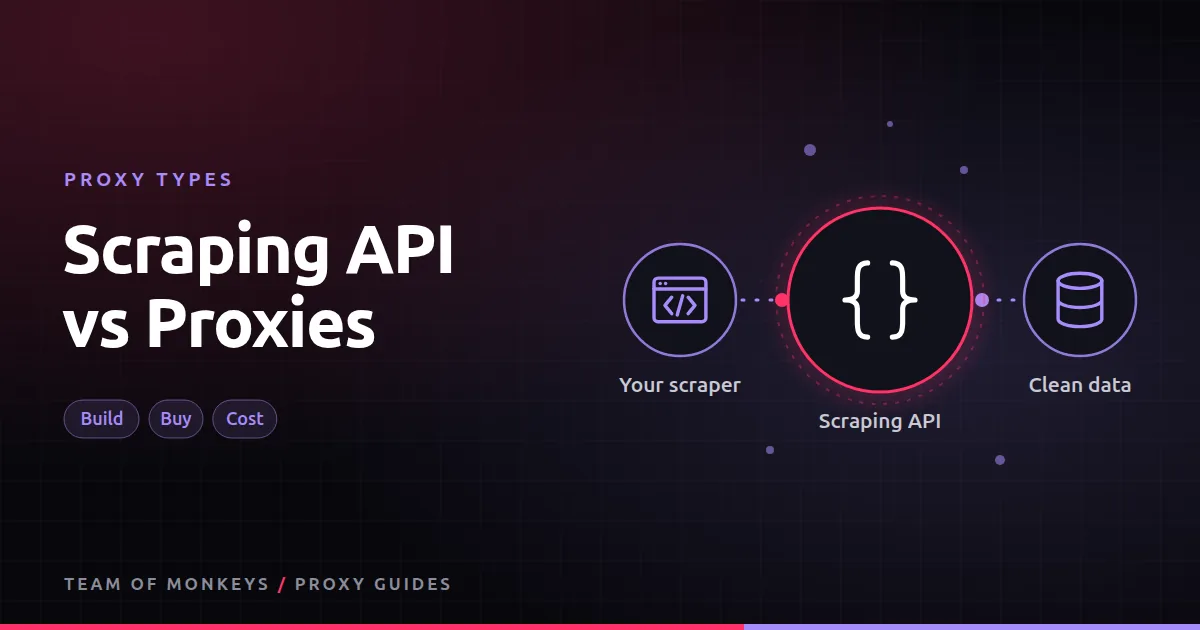
- Use a scraping API: send a URL, get back HTML, rendered HTML, screenshots or structured JSON. The API handles proxies, retries, browsers and CAPTCHAs.
Popular scraping APIs include ScraperAPI, ScrapingBee, Zyte API, and the scraper APIs from large proxy providers like Bright Data and Oxylabs.
Comparison
| Factor | Raw proxies | Scraping API |
|---|---|---|
| Setup effort | Higher | Very low |
| Maintenance | Ongoing (anti-bot changes) | Provider handles it |
| Cost per request (easy sites) | Very low | Higher |
| Cost per request (hard sites) | Can be high due to failures | Predictable |
| Control over requests | Full | Limited |
| Logged-in sessions, complex flows | Fully possible | Limited or awkward |
| JavaScript rendering | Your browsers, your servers | Included (at a price) |
| Structured output | You parse | Often available for popular sites |
| Throughput | As high as you can engineer | Limited by plan concurrency |
When to choose raw proxies
- You have engineering resources and need maximum control.
- Your targets are mostly easy or moderate.
- You run browser automation with logins, carts or multi-step flows. See Puppeteer proxies.
- Your volume is high enough that per-request API pricing would be expensive.
- You need non-HTTP protocols or unusual request patterns.
When to choose a scraping API
- You need results fast without building infrastructure.
- Your targets are heavily protected and your success rate is poor.
- You need structured data from popular sites (search engines, marketplaces) and the API offers parsers.
- You'd rather pay per successful result than manage failure rates.
A hybrid approach
Many teams use raw proxies for most targets and route only the hardest ones through an API or web unblocker. This keeps unit costs low while avoiding endless anti-bot work on the toughest sites.
Proxy tip: If you're comparing types on your own targets, a provider that offers several of them saves time. Geonode lets you buy residential traffic by the GB, ISP IPs by the month and datacenter traffic by the GB, then compare results side by side. See the Geonode Scraper API.
Cost example
Say you need 500,000 pages a month:
- Easy targets, raw datacenter proxies: a modest monthly cost for IPs plus your server time.
- Easy targets, scraping API: priced per thousand requests; usually several times more expensive.
- Hard targets, raw residential: if success is only 50%, you pay for double bandwidth and spend engineering time.
- Hard targets, scraping API: higher per-request price, but you only pay for successes on many plans.
Run a pilot on a sample of your targets with each approach and compare cost per successful page. See proxy pricing guide.
Questions to decide quickly
Answer these five questions:
- How many distinct target sites? Many moderate sites favour proxies; a few very hard sites favour APIs.
- How hard are the targets? If raw residential success is under about 70% after reasonable tuning, an API is worth pricing.
- Do you need logged-in or interactive flows? If yes, proxies with your own browsers.
- What's your engineering capacity? Little capacity favours APIs.
- What's your volume? Very high volume on easy targets strongly favours proxies.
How scraping APIs are typically priced
- Credits per request, with multipliers for JavaScript rendering, premium proxies or "hard" domains.
- Monthly plans with a credit allowance and concurrency limit.
- Charging only for successful requests on many plans.
Read the multiplier tables carefully. A plan advertised at a low price per 1,000 requests can cost many times more on targets that need rendering and premium proxies.
Integrating a scraping API
Most APIs work in one of two ways:
import requests

# 1. URL-as-parameter style
r = requests.get("https://api.scraper.example.com/",
                 params={"api_key": "KEY", "url": "https://target.com/page", "render": "false"})

# 2. Proxy-mode style (the API acts like a proxy endpoint)
proxy = "http://KEY:render=false@proxy.scraper.example.com:8001"
r = requests.get("https://target.com/page", proxies={"http": proxy, "https": proxy}, verify=False)
Proxy mode lets you drop the API into existing scrapers with minimal changes, but usually requires trusting the provider's TLS interception.
Budget tip: For jobs where a fixed IP list is enough, Webshare is one of the cheapest options: shared datacenter proxies are sold by the IP, and static residential (ISP) proxies cost well under a dollar per IP per month at the time of writing. More in Webshare for web scraping.
Hybrid architecture
targets → router
  ├─ easy targets      → datacenter proxies (cheapest)
  ├─ moderate targets  → residential proxies
  └─ hard targets      → scraping API / unblocker
Track success and cost per target and move targets between tiers as conditions change. See proxy rotation strategies and best proxies for web scraping.
Keeping your options open
Whichever route you choose, design so you can change your mind later. Lock-in in data pipelines rarely comes from contracts; it comes from code that assumes one vendor.
- Put fetching behind one function. Something like
fetch(url, country, render)that returns the body and some metadata. Behind it you can call raw proxies, a scraping API or an unblocker, and switch per target without touching the rest of the pipeline. - Store raw responses. Keep the HTML or JSON you received, at least for a while. If you change vendors, you can rerun your parsers on old data to check nothing has shifted.
- Own your parsers. Vendor-supplied structured output is convenient, but if downstream systems depend on its exact format, moving away means rewriting them.
- Keep a second vendor warm. Route a small percentage of traffic through an alternative, so you always have current performance data and a tested fallback.
- Track cost per successful record per target, not just the monthly invoice. It's the number that tells you when to move a target from one route to another.
This is the same discipline that works for proxy providers in general; see how to choose a proxy provider and, at larger scale, enterprise proxy providers. Search engines are the classic case where an API often wins; see Google SERP scraping proxies.
Choosing between providers for this? Our Webshare vs Geonode for Scraping APIs comparison shows where each one is stronger, with costs for typical workloads.
If you're weighing Rayobyte as well, Rayobyte Scraping API explains which of its products fits, and Rayobyte vs Geonode vs Webshare for Managed Scraping puts it side by side with Geonode and Webshare.
Residential tip: If you want to try this on an ethically sourced residential pool, Rayobyte offers a free trial with no credit card, then pay-as-you-go traffic from $3.50 per GB that drops to $0.70 per GB at 1 TB. See the Rayobyte Scraping API.
Key takeaways
- Raw proxies give control and the lowest unit cost on easy and moderate targets; scraping APIs trade cost for convenience on hard targets.
- Logged-in, interactive and multi-step flows are usually better with your own browsers and proxies.
- Compare cost per successful page, including engineering time, not headline prices.
- Watch credit multipliers for rendering and "premium" domains in API pricing.
- Hybrid setups route easy targets through proxies and only the hardest through APIs or unblockers. See web unblocker proxies.
If you decide to build, residential proxies are the usual foundation for a scraper, and our best proxies in 2026 guide helps you pick a provider for it.
FAQ
Do scraping APIs use proxies?
Yes. They run large proxy pools (often residential) behind the scenes.
Are scraping APIs better for Google?
Dedicated SERP APIs are often the easiest way to get Google results. See Google SERP scraping proxies.
Sources and further reading
Independent references that back up the points above, from standards bodies, governments, universities and non-profits. They open in a new tab.
- Downloader Middleware (Scrapy documentation): Scrapy's documentation for the middleware where proxy rotation lives.
- Automated Threats to Web Applications (OWASP): OWASP's catalogue of automated threats, including scraping and scalping, as site owners see them.
- Introduction to robots.txt (Google Search Central): Google's own guide to how it reads robots.txt.
- urllib.request documentation (Python Software Foundation): Python's standard library documentation, including ProxyHandler.
- RFC 768: User Datagram Protocol (IETF / RFC Editor): The 1980 UDP specification, the transport SOCKS5 UDP and HTTP/3 rely on.
Editorial note: Proxy providers change their pools, features and prices often, so treat any figures here as typical ranges at the time of writing and confirm current terms with the provider before you buy.